Frontier models like GPT-6 Astra and Gemini 4 Argon can control robots, but how much does the harness around them affect performance? Coding agents use text-based SKILL.md files to carry task-specific knowledge. We wanted to see whether the same idea could improve robotic manipulation.
We first tested Astra, Argon and Fable on 40 LIBERO tasks, with five attempts per task and model. With planning, rationale and memory enabled, but no task-specific skills, they achieved 174/600 native successes—29%. Some tasks were never completed.
The Nomad harness
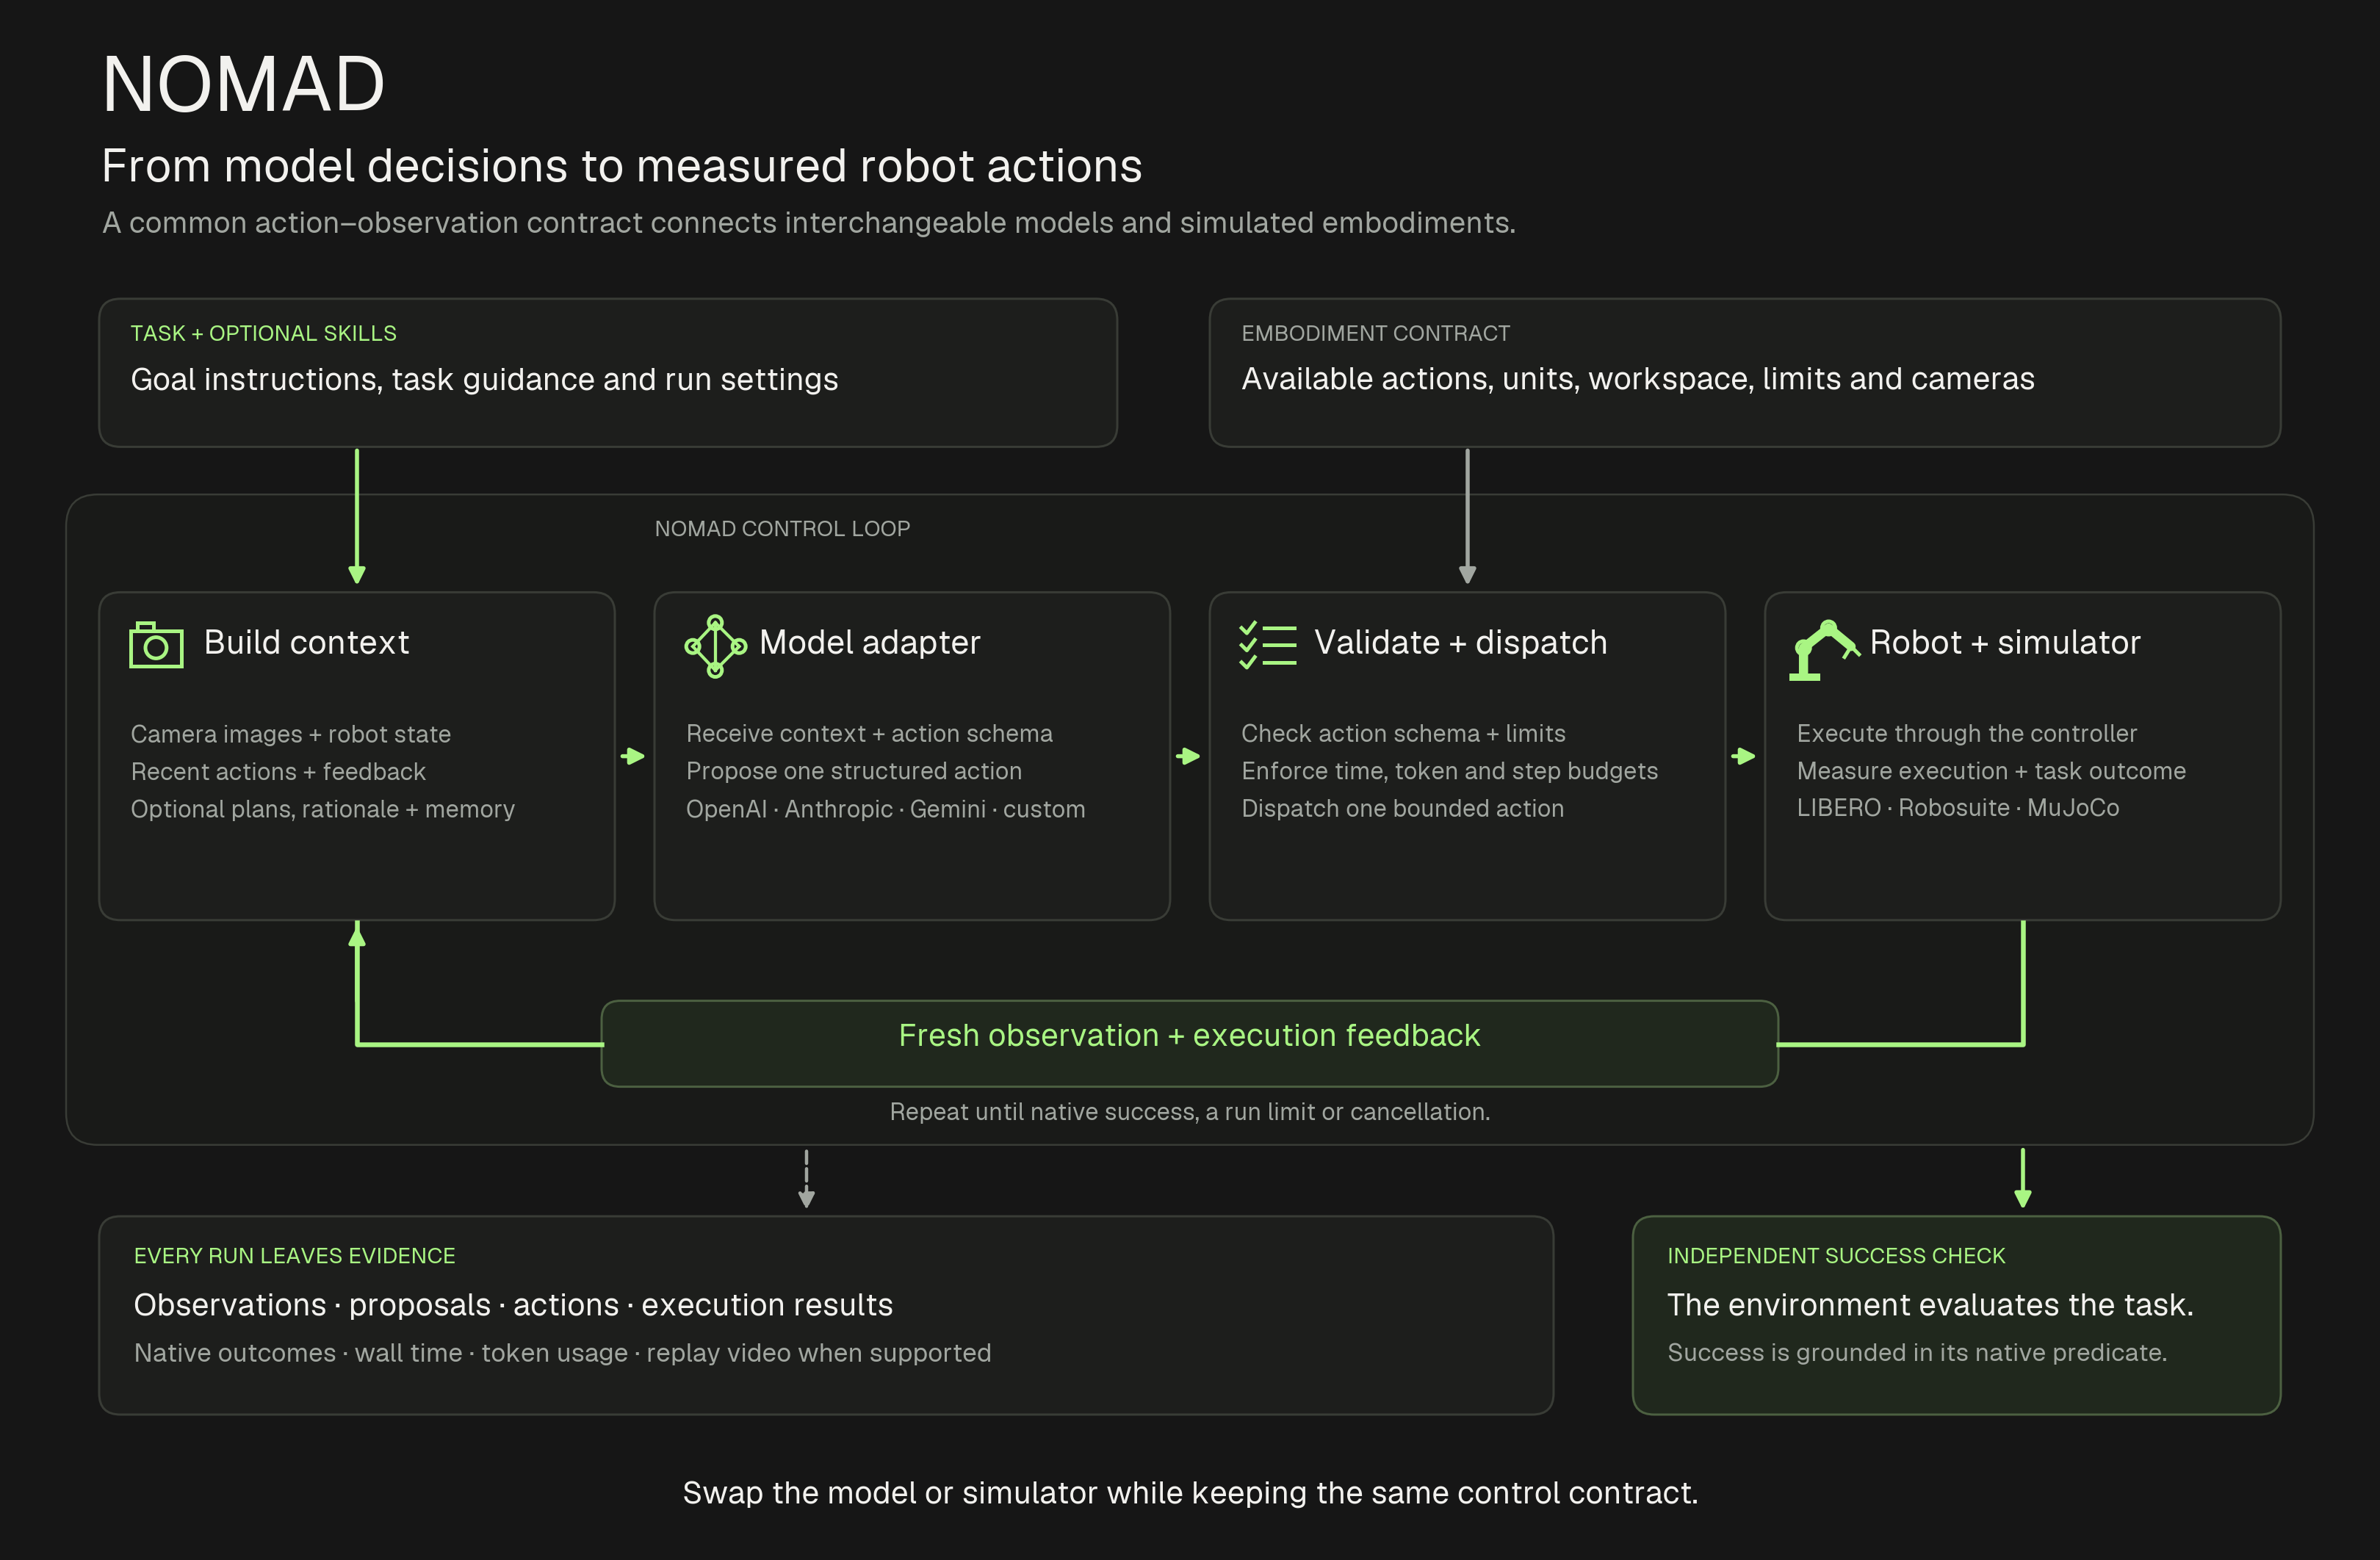
Nomad connects model providers to simulated robots through a common control loop. The model receives camera images, robot state and feedback from its previous actions. It proposes one bounded action at a time, such as moving the end effector or closing the gripper.
Nomad checks the action against the robot’s limits, sends it to the simulator, then returns a fresh observation and execution feedback. The environment’s native task predicate determines success. Each run records the actions, outcomes, wall time and token usage, with video when supported.
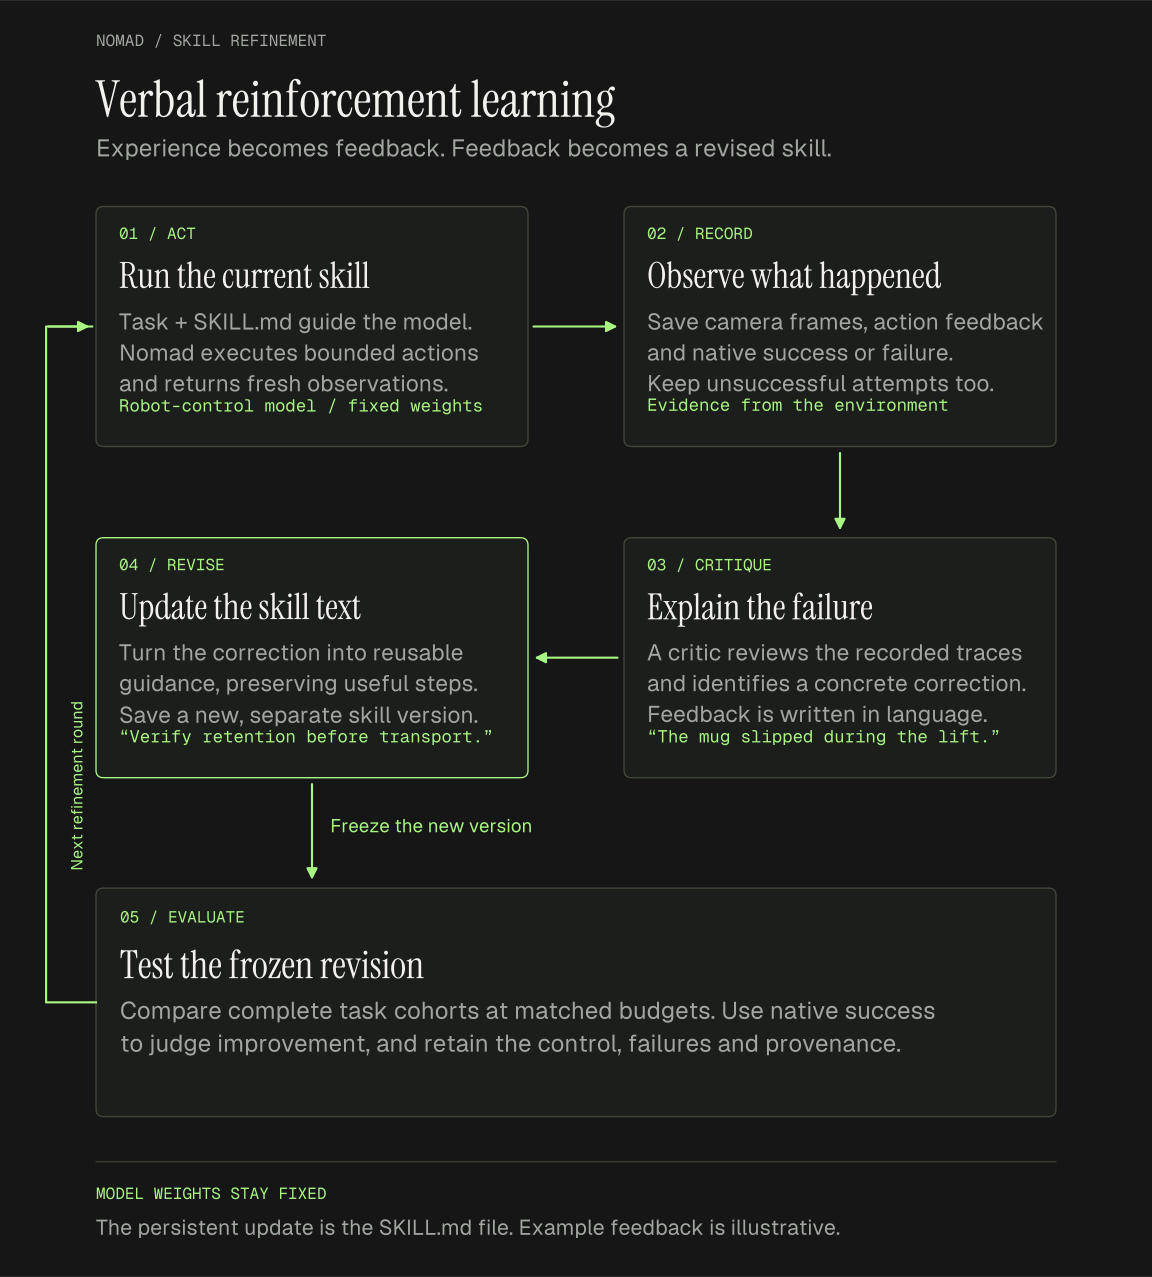
A task skill is additional text passed to the model. It can describe a grasp, a sequence of steps or how to recover from a failure. In these experiments, skills changed the instructions; the robot controller and success criteria stayed fixed.
Developing skills on three tasks
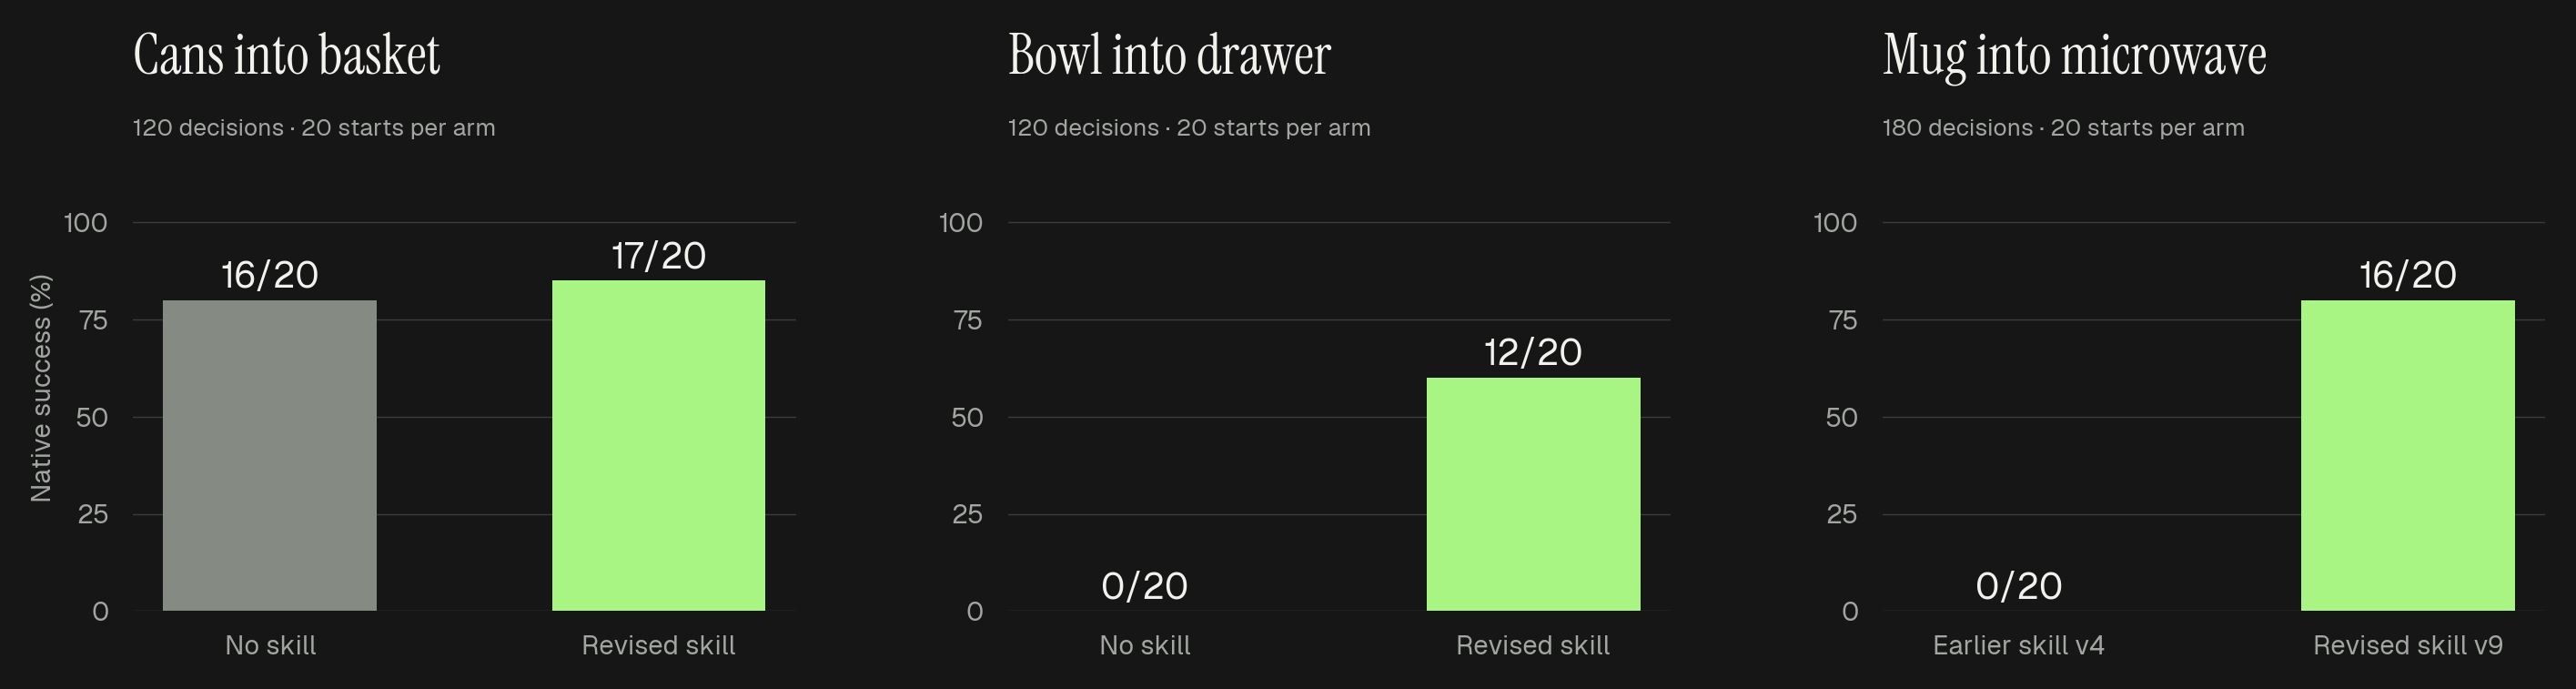
We started with three tasks: two cans into a basket, a bowl into a drawer and close it, and a mug into a microwave and close it. In the initial 20-run no-skill controls, Astra never completed the drawer or microwave tasks.
A critic agent—GPT-6.1 Sol in Codex—reviewed failed traces and wrote a SKILL.md file for the robotics agent. We evaluated the skill, returned the new traces to the critic, and repeated the process. Each evaluated skill version was frozen before its comparison.
The drawer skill reached 12/20 successes, compared with 0/20 without a skill, at the same 120-decision budget. The microwave needed more refinement: version 9 reached 16/20, compared with 0/20 for version 4, with both versions given 180 decisions. No model weights were changed.
Expanding to the full suite
We then expanded skill development across all 40 LIBERO tasks and completed three confirmation rounds. For each task, we chose the best observed complete 15-attempt skill cohort, whether it used the original skill or a revision. One cohort was selected across all three models; every success and failure in it was retained. Ties favored the lower token budget, then a fixed batch order.
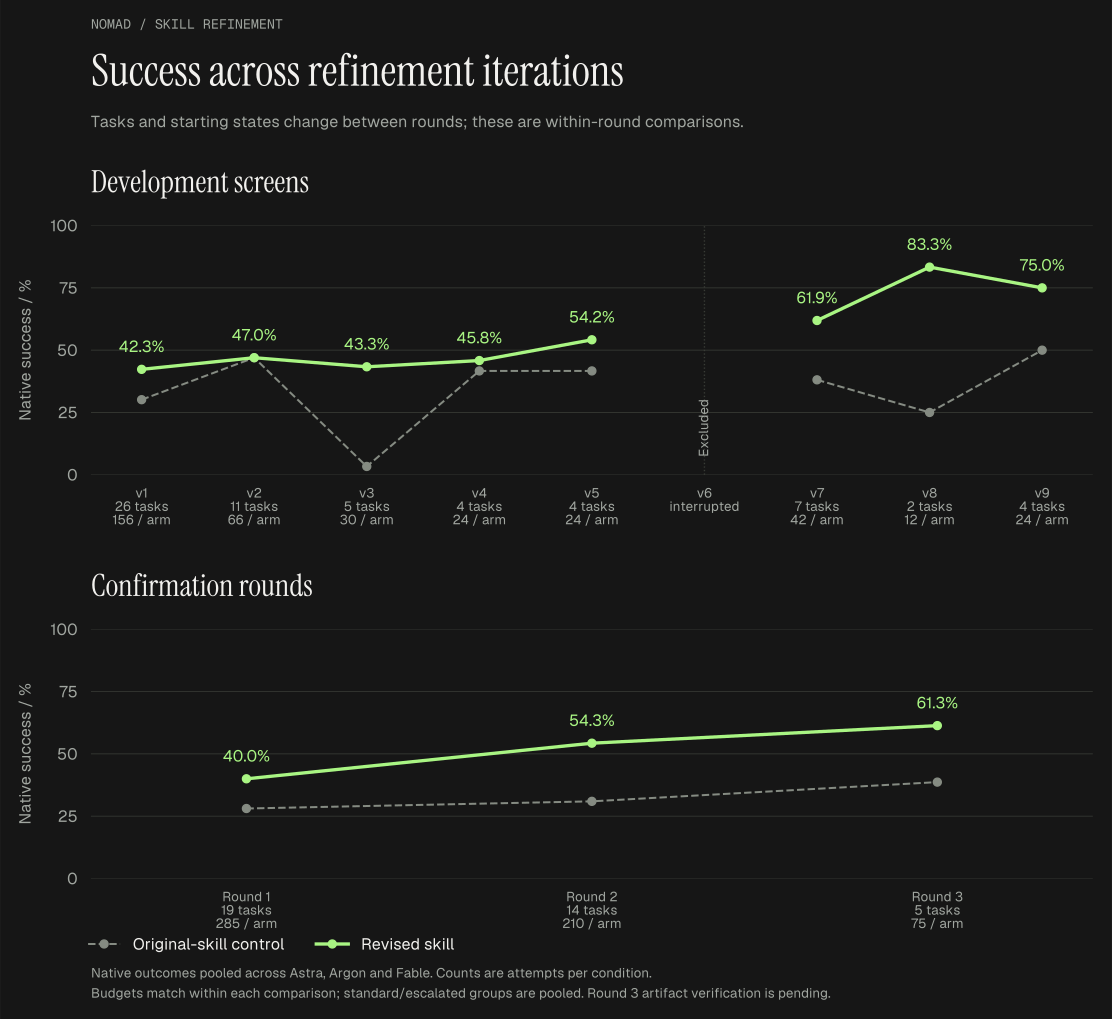
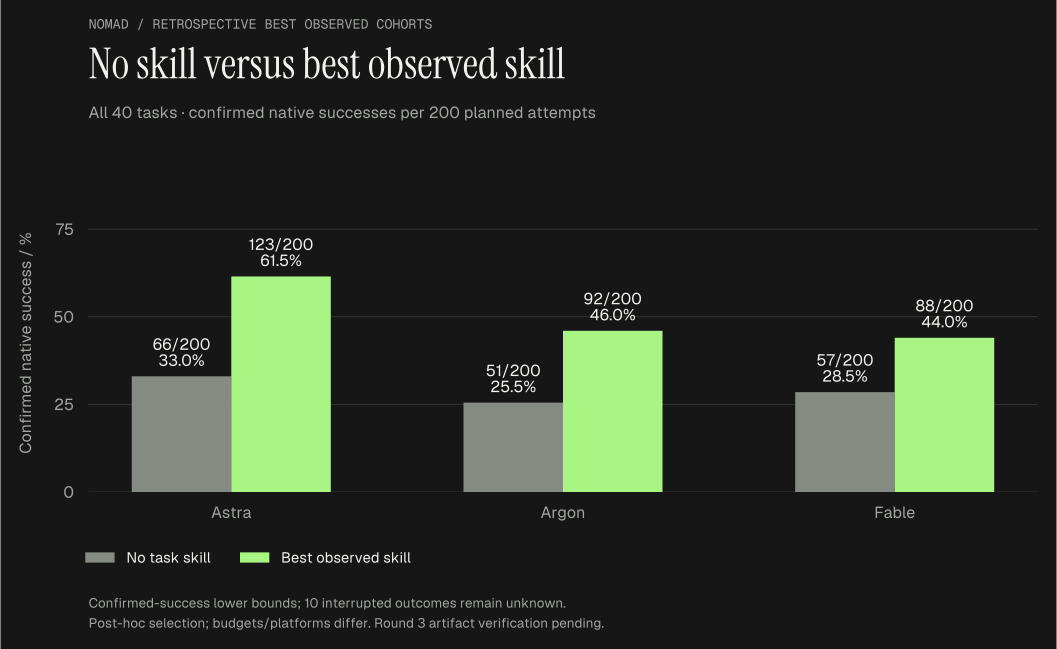
Thirty-five tasks have complete skill cohorts. On those same tasks and starting states, no skill achieved 152/525 native successes (29.0%), compared with 283/525 (53.9%) for the best observed skill cohorts.
The full suite has 200 planned attempts per model. For the five tasks without a complete skill cohort, we retain the original-skill attempts, including 10 infrastructure interruptions. The table reports confirmed successes out of 200 planned; interrupted outcomes remain unknown, rather than task failures.
| Model | No skill /200 | Best skill: confirmed /200 |
|---|---|---|
| Astra | 66/200 · 33.0% | 123/200 · 61.5% |
| Argon | 51/200 · 25.5% | 92/200 · 46.0% |
| Fable | 57/200 · 28.5% | 88/200 · 44.0% |
What this shows
Adding a skill was not enough. The first skill catalog reduced matched success from 165/562 without skills to 142/562 with skills. Failure-driven revision produced much stronger results on selected tasks.
The best-observed comparison selects cohorts after seeing their outcomes, sometimes across several evaluations of the same skill. It is a retrospective performance envelope, not a single evaluated benchmark. It also combines skill and budget effects: historical no-skill runs had 100 calls and 25 minutes; later skill runs had 180 calls and 45 minutes, or 240 calls and 60 minutes for selected tasks. Fable changed from macOS GLFW to Linux OSMesa. These adaptive, in-sample results do not establish held-out generalization or isolate the effect of skill text.
Text-based skills look useful for robotic manipulation, especially when they address failures visible in the traces. The next test is whether the frozen skills transfer to new models.
All 40 task results · Model statistics · Detailed analysis
Working report: third-round success and wall time come from complete host snapshots; full artifact verification remains pending. API costs are usage-based estimates and exclude VM rental and unreported usage. Infrastructure interruptions are retained separately from task failures.